 EN
 All others
0%


Rent GPU servers for large language model training, fine-tuning and inference. Choose ready or custom configurations with the VRAM, GPU count, CPU, RAM and storage your workload requires, with hourly or monthly billing on supported servers.
Use high-memory NVIDIA or AMD GPU configurations for LLM development, private model workloads and production inference where your software stack supports the selected accelerator.
Compare LLM GPU server configurations by GPU model and VRAM, GPU count, CPU, RAM, NVMe storage, network, location, availability and current pricing. Choose hourly or monthly billing on supported servers, or build a custom configuration for your LLM workload.
The selected collocation region is applied for all components below
All
Iceland
IS

France
FR
Netherlands
NL
Germany
DE
Finland
FI
USA
US
Russia
RU
The right GPU depends on model size, precision or quantization, VRAM requirements, context length, concurrency and whether you are training, fine-tuning or serving a model. Use the comparison below as a starting point, then check current HOSTKEY configurations and availability.
|
GPU / VRAM |
Best fit |
Training / fine-tuning |
Inference |
Notes |
|---|---|---|---|---|
|
RTX 4090 / 24 GB |
Development, quantized models, smaller LLM workloads |
Moderate |
High if workload fits VRAM |
Current inventory; no generic NVLink claim |
|
RTX 5090 / 32 GB |
Higher-memory LLM development and inference |
Moderate |
High |
Blackwell; verify exact server configuration |
|
RTX A6000 / 48 GB |
Professional AI/LLM development, larger single-GPU workloads |
Medium–High |
High |
Confirm inventory / multi-GPU support |
|
NVIDIA A100 / 80 GB |
Data-center training, fine-tuning and inference |
High |
High |
Exact variant/interconnect must match HOSTKEY SKU |
|
NVIDIA H100 / 80 GB |
Demanding data-center training and high-throughput inference |
Very high |
Very high |
No generic benchmark multipliers |
|
RTX PRO 6000 Blackwell / 96 GB |
High-VRAM professional AI/LLM workloads |
High |
High |
Confirm exact HOSTKEY SKU/naming |
|
AMD Radeon AI PRO R9700 / 32 GB |
AMD LLM workloads where stack is supported |
[CONFIRM] |
[CONFIRM] |
Confirm ROCm / llama.cpp / serving-stack compatibility |
|
AMD Radeon RX 7900 XTX / 24 GB |
Selected inference/development with supported AMD stack |
[CONFIRM] |
[CONFIRM] |
Compatibility caveat required |
Start with a clean operating system or use supported pre-installed environments for AI, machine learning and data workloads. Available tools may include PyTorch, TensorFlow, JupyterLab, Anaconda, Apache Spark and Apache Airflow. Explore AI Platform and Pre-installed Apps
 NL

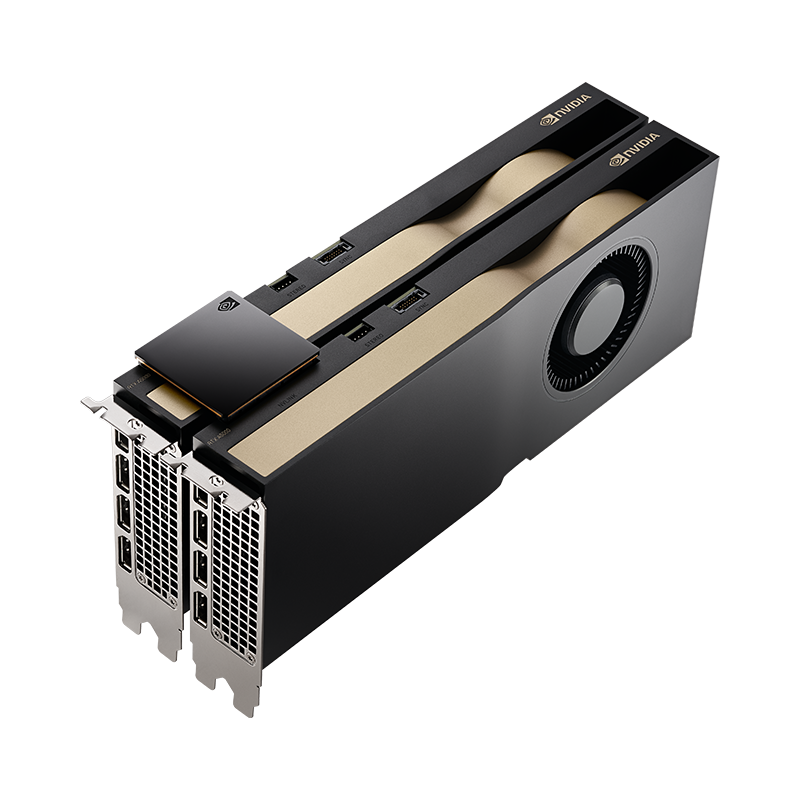
Custom dedicated server with cutting-edge GPU cards like the RTX A4000 / A5000 / A6000 / 5090 / 6000 PRO
 EU
 USA

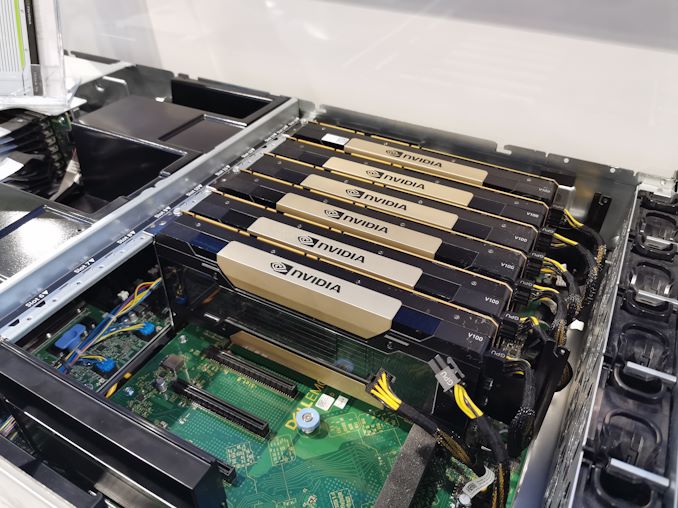
Pre-configured GPU dedicated servers based on professional cards like the RTX A4000 / A5000 / A6000 / 5090 or more budget-friendly options from previous generations.
EU USA 
The GPU card in virtual servers is dedicated to the VM and its resources are not shared among other clients.
Address:
W. Frederik Hermansstraat 91, 1011 DG, Amsterdam, The Netherlands
Order: hostkey.com

Address:
W. Frederik Hermansstraat 91, 1011 DG, Amsterdam, The Netherlands
Order: hostkey.com
Address:
W. Frederik Hermansstraat 91, 1011 DG, Amsterdam, The Netherlands
Order: hostkey.com
Rent instant server with RTX 5090 GPU in 15 minutes!
 High-VRAM GPU Options
 Single- and Multi-GPU Configurations
 Flexible Hourly and Monthly Billing
 Fast NVMe Storage and Networking
 Pre-installed LLM Environments
 Full Server Control
 Infrastructure Protection
 24/7 Technical Support
 High-end Green technologies
 Traffic
 Free DDoS protection
 IP addresses
 Customer support 24/7
 Pre-installed software



There is no single best GPU for every LLM workload. H100 and A100 can suit demanding data-center training or high-memory inference, while RTX 5090, RTX 4090 and professional GPUs may fit smaller, quantized or development workloads. Choose by model size, precision or quantization, VRAM, context length, GPU count and budget.
Renting avoids upfront hardware purchase and lets you choose different server configurations as requirements change. Compare rental cost with expected utilization, project duration and the operational cost of owning hardware.
Yes, the same GPU family can often support both, but the best configuration can differ. Training emphasizes memory and sustained compute; inference may prioritize latency, throughput, concurrency and cost per request.
VRAM depends on model size, precision or quantization, context length, batch size, KV cache and serving overhead. Use model-specific requirements rather than a single minimum-VRAM rule.
Yes. Custom configurations can combine supported GPUs with the CPU, RAM, NVMe storage and networking required for the workload. Availability and delivery time depend on selected hardware.
Multi-GPU configurations are available for selected models. GPU count and interconnect options depend on the exact server configuration; confirm NVLink or other interconnect support before ordering.
Ready in-stock configurations may be available from 15 minutes. Custom hardware requires additional provisioning time depending on components and location.
HOSTKEY provides 24/7 technical support for server and network issues. Managed software or application-level assistance depends on the selected support/service scope.
| Location | Server type | GPU | Processor Specs | System RAM | Local Storage | Monthly Pricing | 6-Month Pricing | Annual Pricing | |
|---|---|---|---|---|---|---|---|---|---|
| NL | Dedicated | 1 x GTX 1080Ti | Xeon E-2288G 3.7GHz (8 cores) | 32 Gb | 1Tb NVMe SSD | €170 | €160 | €150 | |
| NL | Dedicated | 1 x RTX 3090 | AMD Ryzen 9 5950X 3.4GHz (16 cores) | 128 Gb | 480Gb SSD | €384 | €327 | €338 | |
| RU | VDS | 1 x GTX 1080 | 2.6GHz (4 cores) | 16 Gb | 240Gb SSD | €92 | €86 | €81 | |
| NL | Dedicated | 1 x GTX 1080Ti | 3.5GHz (4 cores) | 16 Gb | 240Gb SSD | VDS | €94 | €88 | €83 |
| RU | Dedicated | 1 x GTX 1080 | Xeon E3-1230v5 3.4GHz (4 cores) | 16 Gb | 240Gb SSD | €119 | €112 | €105 | |
| RU | Dedicated | 2 x GTX 1080 | Xeon E5-1630v4 3.7GHz (4 cores) | 32 Gb | 480Gb SSD | €218 | €205 | €192 | |
| RU | Dedicated | 1 x RTX 3080 | AMD Ryzen 9 3900X 3.8GHz (12 cores) | 32 Gb | 480Gb NVMe SSD | €273 | €257 | €240 |
Large language models rely on highly parallel matrix operations and substantial memory capacity, which makes GPUs a practical choice for training, fine-tuning and inference. The right configuration depends on the model, precision or quantization, context length and expected workload rather than on a single “best” accelerator.
HOSTKEY lets you rent GPU servers with current NVIDIA and AMD accelerators, different VRAM capacities, and single- or multi-GPU configurations where supported. This gives teams access to LLM compute without purchasing and maintaining high-end hardware. Hourly or monthly billing is available on supported configurations, while ready and custom servers provide different trade-offs between deployment speed and hardware flexibility.
For LLM workloads, evaluate more than raw GPU performance. VRAM capacity determines whether model weights and runtime memory can fit; memory bandwidth affects how quickly data moves; context length and concurrency increase KV-cache requirements; and software compatibility can differ across NVIDIA and AMD environments.
There is no universal best GPU for local LLM use. Consumer and professional cards such as RTX 4090, RTX 5090 or higher-VRAM professional GPUs can be practical for experimentation and smaller or quantized models, while larger workloads may require data-center accelerators or multiple GPUs.
VRAM should be the first constraint to check, but it is not the only one. Model size, quantization level, context length, batch size and serving concurrency all affect memory use. A configuration that runs a model for one developer may not provide enough headroom for production serving or long-context workloads.
“Local LLM” usually means that the model runs on hardware controlled by the user rather than through a third-party model API. A rented dedicated GPU server is still remote infrastructure, but it can provide a self-managed environment with administrative control. If physical on-premises hardware is required, a hosting rental page should not be presented as a substitute for a local workstation or server.
Buying local GPU hardware can make sense when a team needs permanent physical control of the machine, has stable long-term utilization and can operate power, cooling, networking and maintenance itself. Local systems can also be useful for individual experimentation when the target models fit within available VRAM.
Renting a GPU server avoids the upfront hardware purchase and lets a team choose from available GPU configurations without maintaining the physical infrastructure. It can be useful for temporary training or fine-tuning projects, production inference, remote development environments, or workloads that need more GPU memory than a local workstation provides.
The decision should be based on total utilization, required VRAM, project duration, data-handling requirements and operational responsibility. HOSTKEY provides dedicated and virtual GPU infrastructure; it should not be described as an elastic serverless GPU cloud unless those capabilities are explicitly supported.
Start with GPU memory. The model weights must fit alongside runtime memory, activations during training or fine-tuning, and KV cache during inference. Quantization can reduce memory requirements, but the result depends on the model and serving stack.
Memory bandwidth is another key factor because LLM inference frequently moves large volumes of model data between GPU memory and compute units. For production serving, context length, concurrent requests, batch size and latency targets can matter as much as the nominal GPU model.
For larger jobs, multiple GPUs can provide more aggregate compute and memory, but scaling depends on the software framework, model parallelism strategy and the available interconnect. Do not assume that every multi-GPU server provides NVLink.
Finally, verify software compatibility. NVIDIA CUDA environments have broad framework support, while AMD acceleration depends on the exact GPU, ROCm/runtime version and application stack. Before ordering, match the GPU and server configuration to the model, framework and serving engine you actually plan to use.
 +31 20 820 3777
 Compliance & KYC
 Support
 Documentation

 Login